Local LLM London: Managed, On Your Own Site
Every London firm has someone who could run a language model on a spare machine, and a contractor who charges London rates to keep it alive. This is the version where neither has to.
£500 per month for the software and the hardware rental. You rent the machine — you don’t buy it.
A local LLM in London is a large language model running on a machine at your own premises rather than a provider’s cloud, so prompts and documents never leave your office. We shortlist and test open-weight local LLM models against your documents, specify the machine, install it on site across Greater London and manage the updates.
Find out which model suits the job
A short call to match the model and machine to the work. If a DIY setup would genuinely do, we will tell you.
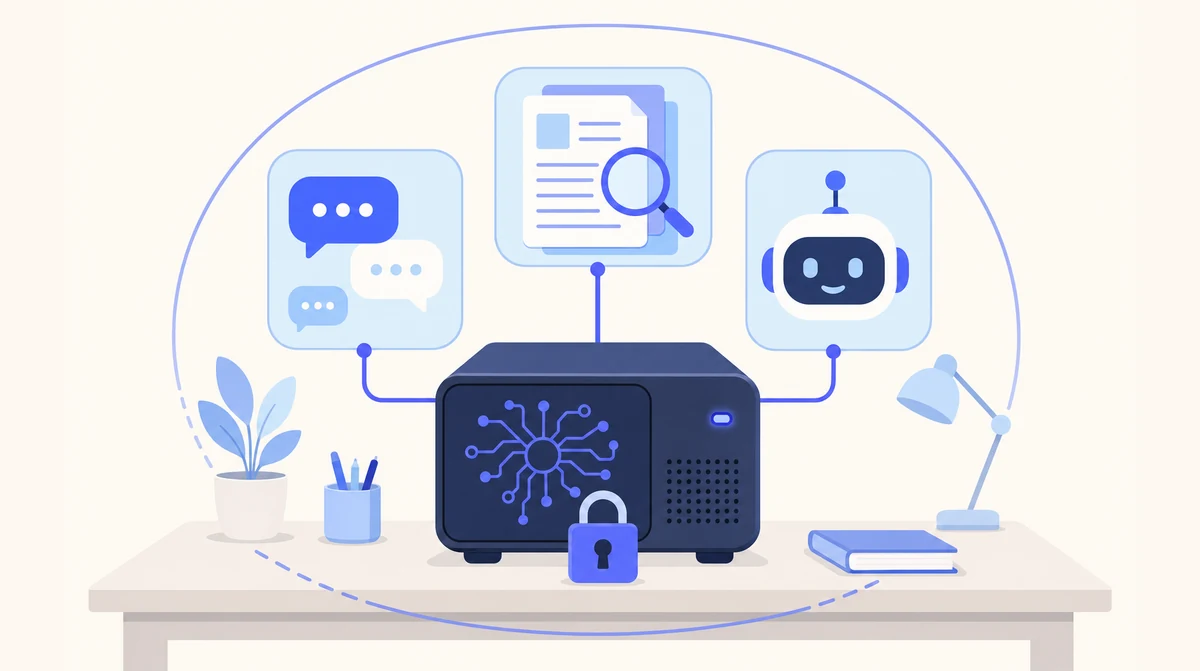
One machine at your London premises, an open-weight model sized for the team, and the chat, document and assistant tools around it.
Cloud Agents for the Phone and Inbox, Local AI for the Files
Many London businesses pair the two: hosted agents answering calls and sorting email from day one, and a Local AI machine on site for anything that must not leave the office.
- ☁ Cloud-based AI Receptionist
- ☁ Cloud-based Email Manager
- ☁ Cloud-based Leads Outreach
- 🏢 On-premise Local AI
Do It Yourself, or Have It Done
Running a local LLM is not hard for an afternoon. Running one for London firms, every working day, with backups and someone to ring, is a different job.
| DIY on a spare machine | Cloud LLM subscription | Managed local LLM in London (ours) | |
|---|---|---|---|
| Where prompts and files go | Your machine | The provider’s servers | Your machine |
| Choosing local LLM models | Trial and error, evenings | No choice | Tested against your documents by us |
| Hardware | Whatever is spare | None | Specified for the team and rented to you |
| Reads your document library | If you build it | Only what is pasted in | Document spaces with citations |
| Model upgrades and updates | You, when you remember | Automatic | Us, as part of support |
| When it breaks | You | Their status page | Restored from backup by us |
Which Model, Decided by Your Documents, Not a Leaderboard
London firms tend to arrive at a local LLM with a name already in mind, because someone read a benchmark. The honest answer is that the benchmark did not read your documents. A firm in the City working through cross-border agreements needs a model that is precise on long, structured English contracts. A Harley Street clinic drafting correspondence needs one that writes well and stays in the practice’s tone. An agency in Shoreditch summarising research decks needs one that handles mixed layouts. Those are different choices, and the machine has to be specified to run whichever it is.
So we do it in the order that works. A short call about what the model will read and for whom. A shortlist of open-weight candidates — Llama, Mistral, Gemma, Qwen and others come in several sizes each — and a machine specified to run the largest of them well for your team size. Then, once the machine is installed at your premises and your documents are imported into spaces, we test the shortlist against a sample of your real files and settle on one.
What you get is the model plus everything a team needs around it: a private chat assistant, document spaces that search and summarise across hundreds of files with citations to the page, custom assistants for the recurring jobs, and sign-in through the Microsoft 365 or Google Workspace accounts your staff already have. Nothing goes to a cloud provider; the only outside connection is your own sign-in.
And what you do not get is a maintenance job at London contractor rates. Model upgrades arrive regularly and a careless one changes the answers your team has learned to expect, so upgrades are made with you as part of support, from the people who did the install. If a spare PC and a free afternoon would genuinely do for one technical person, we will say so on the call.
The Model Is the Engine. This Is the Car.
A bare model is a demo. London firms need the machine, the tools around the model, the sign-in and someone to maintain it.
A model matched to the work
An open-weight local LLM chosen and tested against your own documents, on a machine specified to run it well for your team size.
Document spaces around it
The model on its own answers from what you paste in. Spaces let it search, summarise and compare across hundreds of your files, citing the page each answer came from.
Chat and assistants on top
A private chat assistant for the team and custom assistants for the recurring jobs, all running on the same machine as the model.
| Document | What a London team asks for | What stays where |
|---|---|---|
| Client files under restrictive engagement terms | Search, summarise, draft against | On the machine, in your office |
| Cross-border matter correspondence | A chronology or summary, cited to the page | On the machine, in your office |
| Contracts and agreements | What clause 14 says; the differences between versions | On the machine, in your office |
| Patient or client correspondence | A draft reply in your wording | On the machine, in your office |
| Internal policies and templates | Find it, cite it, draft from it | On the machine, in your office |
| Your practice, case or CRM system | Not connected — remains the system of record | Your existing system |
From First Call to a Working Model at Your London Premises
Weeks, not months. Most London clients start with one team — one practice area, one department — and widen from there.
Size and check the site
A short call on who will use it and what it will read. We specify the machine and, for serviced offices and shared buildings, check how the network is arranged.
Install at your premises
The machine goes on your network anywhere in Greater London. Single sign-on connects to your Microsoft 365 or Google Workspace and your documents are imported into spaces.
Train on site, then support
We train the people using it at your office, then keep the software updated and the models current, with support from the people who did the install.
Where Local AI Is the Wrong Answer
We would rather lose the enquiry than the trust. Three things we tell every prospect before they sign anything.
It is not a frontier model
The largest cloud models are still ahead of any local LLM on hard, novel reasoning. If your work needs that, a local model is the wrong tool and we will say so. For summarising, drafting and answering questions about your own documents, most offices are happy with it.
It is slower than the big cloud models
Open-weight models on a single machine are capable for summarising, drafting and answering questions about your own documents. For frontier reasoning on hard, novel problems, the largest cloud models are still ahead. That is the trade.
It is a weeks-long install, not a sign-up
A cloud agent is live in days. Local AI needs the machine specified, delivered, installed on your network and your documents imported. Weeks, not months — but not tomorrow.
We Run Our Own
Chosen against your files
Model selection is tested on a sample of your own documents, not a public leaderboard.
Sized with the model
The machine and the model are specified together. A model the hardware cannot run well is the commonest DIY mistake.
Upgrades made on purpose
Model upgrades are part of support, so someone is deciding when the answers your team relies on are allowed to change.
UK data protection built in
No third-party AI processor and no restricted transfer for the AI step. UK GDPR, the Data Protection Act 2018 and the ICO as regulator, with a data processing agreement for the support access you grant us.
Which Page Answers Your London Question
| If your question is… | The short answer | Read more |
|---|---|---|
| How is the model chosen in general? | Tested against your documents, not a leaderboard | Local LLM |
| We want the Local AI overview for London | The head page for the capital | Local AI London |
| What exactly is installed? | One machine, on site, supported | On-Premises AI London |
| Is this what people mean by private AI? | Yes — the model is what makes it private | Private AI London |
| We would rather host it ourselves | It sits in your building; we maintain it | Self-Hosted AI London |
| We are in Manchester, not London | Managed local LLMs across Greater Manchester | Local LLM Manchester |
| Why on-premises at all? | The case for Local AI, in full | Local AI product page |
Local LLMs in London: Common Questions
What is a local LLM?
A large language model — the kind of model behind chat assistants — running on hardware you control rather than accessed through a provider’s service. Your prompts, uploaded documents and chat history stay on that machine in London.
Which local LLM models do you install?
It depends on the job. Drafting and summarising, answering questions across a document library, and structured extraction each favour different open-weight models, and the machine has to fit the model. We shortlist and test candidates against a sample of your own documents during setup.
Can a local LLM cope with a London firm’s document volume?
Document spaces are built for hundreds of files each, searched and summarised with citations. A larger document set means a larger machine and sometimes a different model, both of which are decided on the first call — not a different product.
Will it be slower than the cloud services our staff use now?
Somewhat, and we say so before you sign anything. For summarising, drafting and answering questions about your own documents, most London offices are happy with it. For frontier reasoning on hard, novel problems, the largest cloud models are still ahead.
Do you install on site in London?
Yes. The machine is specified after a short call, then installed on your network at your premises anywhere in Greater London. We connect your existing Microsoft 365 or Google Workspace sign-in, import your documents and train your team on site.
We are in a serviced office. Does that matter?
It is worth raising early. The machine sits on your own network segment, and in a shared building we check how that network is arranged before the install. A question for the first call, not a blocker.
How much does Local AI cost?
£500 per month for the software and the hardware rental. The dedicated machine is rented to your business, not sold: you never buy the hardware. It is installed in your building and runs the private chat, document spaces and assistants. Local AI is for business customers only.
Tell Us What the Model Would Read
One short call to shortlist the model and size the machine for your London office. If a spare PC would genuinely do the job, we will tell you that instead.
Prefer email? sghaith@businessaiagents.co.uk